Projected to month end
Pace-to-budget per account and campaign, not spend to date.
Pacing & anomaly detection
Overspend and broken campaigns are only expensive because they are found late. We build the monitoring layer that watches pacing and performance across all your accounts continuously, and tells the right person while there is still time to act.
What you get
Pace-to-budget per account and campaign, not spend to date.
CPC, CVR, ROAS and impression share against your own seasonality.
Routed to the account manager in Slack or email, with the gap sized.
Leadership can scan exposure across every account.
The problem
Pacing problems are discovered during month-end review, the one moment when nothing can be done about them. The structural reason is that no human can watch three hundred accounts daily, so the check happens on a monthly cadence while the spend happens hourly. Underspend is the quieter version of the same failure: budget the client agreed to that simply never went out the door, invisible because nothing looked broken.
What the system watches
How we work
Model pacing against real budgets and flight dates, including mid-month changes
Baseline each metric on your own history, so thresholds reflect normal variance, not round numbers
Route alerts to the person who owns the account, not a shared channel nobody reads
Replay against past months to prove the system would have caught real incidents before going live
What we use
Related work
We rebuilt the ETL, warehouse and automation layer across Amazon, Walmart, TikTok, Instacart and Criteo.
Read the case study
We built ETL pipelines into one data model and one dashboard for Amazon, Walmart and Instacart campaigns.
Read the case study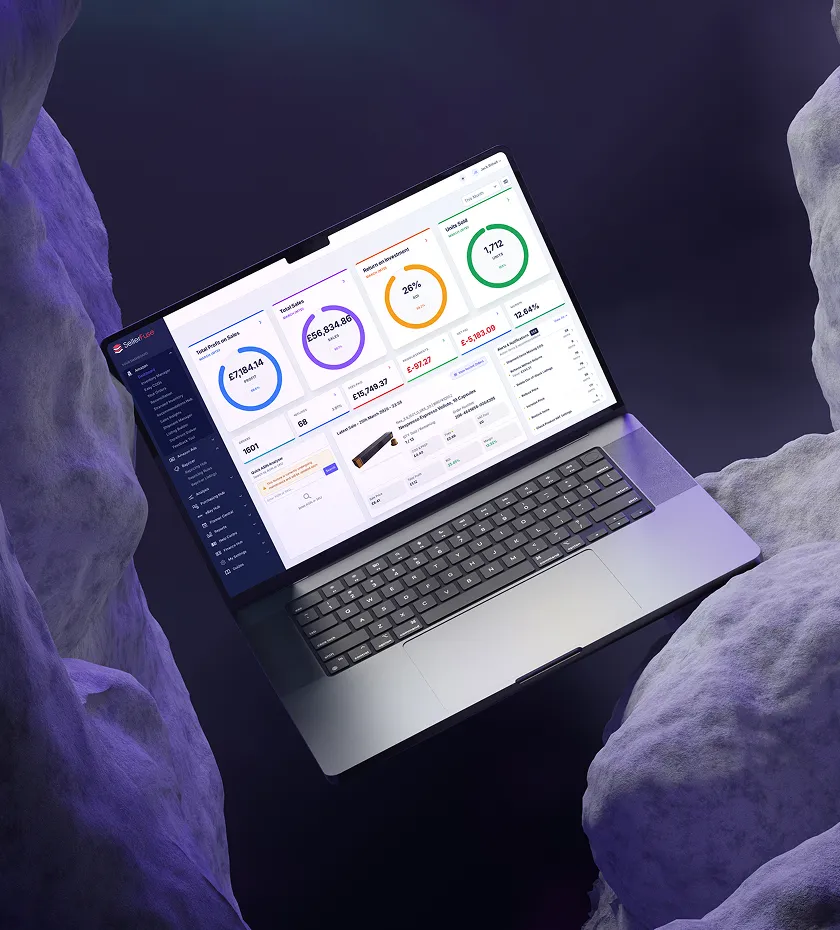
We built the SP-API and Ads API pipelines, live dashboards and automation behind SellerFuse.
Read the case studyFAQ
Platform alerts are per platform, per account and threshold-based, so a client running four channels needs four sets of rules and still has no combined view. This watches the full book in one place, projects to month end rather than reporting spend to date, and detects statistical anomalies rather than only fixed thresholds.
Only if the thresholds are wrong, which is why baselining comes from your history and includes seasonality. We validate by replaying past months: the system should have caught the incidents you remember and stayed quiet the rest of the time. We tune until that holds.
It can, and that is our AI bid and budget agent work. We usually recommend starting with detection and alerting so the team builds trust in the signal, then automating the safe, well-understood responses once it has proven itself.
It runs off your warehouse rather than per-account API polling, so the marginal cost of another account is negligible. We have run this pattern across thousands of accounts.
Go deeper
Guide
A practical breakdown of Amazon PPC automation: how AI bid management, dayparting, and rules engines replace manual campaign work without wasting ad spend.
Read the guideGuide
Scaling an Amazon agency from dozens to thousands of clients breaks manual reporting completely. Here's the infrastructure that makes that scale possible.
Read the guideRelated
Agents that adjust bids and budgets inside your limits, with approval and audit modes.
Learn moreFreshness, volume and schema drift alerts, plus reconciliation to platform figures.
Learn moreOne view across every channel and client, loading in under a second.
Learn moreTell us how many accounts you run and how pacing is checked today, and we will scope the monitoring layer.